Category Archives: Tools

Introduction: Digital Public History

Hello, everyone. I am Lydia Pensel, a second-year PhD student at Southern Illinois University Carbondale. I predominantly study European history, with an emphasis on British history. My experience with digital humanities is relatively limited. The only experience I have outside of the Introduction to Digital Humanities course I took last semester is as the coordinator of the undergraduate podcasting project in my department.

Regarding what interests me in public digital humanities, I am interested in almost every aspect of utilizing and creating digital humanities projects. I have been well versed in technology since I was a young child, and digital humanities provides me the means of combining my two loves, history and technology. Beyond this, I am a staunch advocate for public history because, as an educator, I aim to share my knowledge in an accessible way with the general public to create connections and share information. Both of my parents are educators, so almost every vacation I took as a child included some form of a museum or historical site, which means that public history is deeply ingrained in my life. My learning goals for this semester are relatively simple: to better understand the significance of public history and how digital public history can be disseminated to everyone in an accessible and easy-to-understand manner. I also want to fully understand what public history entails and discover what projects I can use in the future, especially when I finish my PhD.

I look forward to this semester and the valuable information I will learn.
 

Podcasts and the Digital Humanities

Podcasts are part of almost everyone’s daily lives. They not only act as a means of connection to a broader community but also allow for the dissemination of information to the wider public. I feel very passionate about podcasts because I am in charge of my undergraduate history department podcasting project, where I produce, record, edit, and publish podcasts. A podcast has so much potential that it can not be achieved within a regular medium such as text. First, podcasts, particularly historical podcasts, allow listeners to interact directly with the subjects they are learning about. This can be heard through oral histories, interviews, and other forms. As the podcast Throughlines highlighted it the episode “The Lavender Scare,” oral history interviews can be directly shared. This creates a greater intimacy with the audience and a direct connection between the listener and the storyteller. A direct oral interview can be shared, and a reading of the subject works also creates a greater connection. Podcasting also allows for those who are auditory learners to understand better information that they can not as easily comprehend in text form. Beyond this, podcasts are also critical for their ability to be shared with the wider world. One of the most essential aspects of podcasts and digital humanities is accessibility and whether the general public can find work. With a podcast, nothing is more important than sharing your work with the world. This can be shown directly in the project I work with as the undergraduates who participate in the project use their research paper to share with the world and create our own digital form of student-published journal. Their research can reach a wider audience and inform the masses with a podcast.

Podcasts not only exemplify the key factors of digital humanities projects, such as data visualization with Voyant and mapping with Kepler .gl, but they also share projects with the greater public. These projects show how digital humanities scholarship can use a multidiscipline approach to data, information, and sources to create a project with various mediums. Not to mention that podcasts and other digital humanities projects are primarily collaborative and allow for many to work on a project together. This allows for varying perspectives and critical contributions that are not the same in traditional scholarship.  Academic scholarship is outstanding for academics, but digital humanities projects and, specifically, podcasts create a means of disseminating one’s work to a broader audience and, in turn, enriching the lives of others. Intimacy in listening to a subject’s voice, such as a historical figure or just an everyday person, perpetuates the principles of digital humanities and creates something exceptional for the world.

What Can Digital Humanities Do With Crowdsourcing?

Before working specifically with crowdsourcing in the digital humanities within this unit, I was very unfamiliar with community projects such as Transcribe Bentham, which we worked with, and Zooniverse, as mentioned in this unit’s reading by Mia Ridge and her fellow authors. The context I knew of crowdsourcing was mainly similar to crowdfunding projects, where you contribute financially. Once I worked with Project Bentham and By The People, I fully understood the implications and importance of crowdsourced projects within the digital humanities.

First, transcription is the type of task within digital humanities that works well with crowdsourcing. As the projects we specifically worked with showed, using crowdsourcing to view and transcribe documents such as letters, journals, and other written material is valuable. Not only can others view things that some may have missed, but with extensive collections such as the By The People, the more hands involved make for less work for each person. This shares that collection of information with the public, allowing those who may not have much interest in the subject to learn and interact with a person’s works. Another task that works well with crowdsourcing is including data annotations, categorizing, and inputting metadata. Many museums and archives are overwhelmed with the number of items and data that need inputting; thus, if they turn to a crowdsourcing model, they can not only engage in completing these tasks faster but also gain more interest in the wider world. Finally, crowdsourcing to create oral histories and storytelling in the broader community creates a more extensive digital archive. It allows those in the general public to be directly involved in significant events while sharing their own stories. As a historian, I also have to look at the value of recording history for the future as never being a bad thing.

Another aspect of crowdsourcing crucial to the project’s success is engaging and retaining those involved. The most important key to the success of a crowdsourcing project is the user interface; if the software being used is complicated to work with, then the users will stop using it. I intercountered this directly within the Transcribe Bentham, since it was one of the first projects of its kind, the software was complicated to work with. Not only were the images not high quality, but the interface did not allow the user to engage in the work as closely as possible. This highlights how critical it is for interfaces with crowdsourcing material to be simplistic and have the required tools for the user to succeed. In the case of transcription, high-quality images are a must. Beyond the interface, another key factor is that the project needs to have clear goals and outcomes to avoid confusion about what the user is contributing to. Every project must make clear what they want to achieve and what they plan to do with the work when it is completed. Finally, a crowdsourcing project needs clear tutorials, instructions, facts, and support for the users to have all of the tools to be successful in helping the creators achieve their goals. If there are no clear instructions or a support page to assist the users, they will likely not even engage in the project. Crowdsourcing allows many different organizations, archives, and museums to interact directly with the public in a new way that allows both parties to gain and work together, which leads to a brighter future for digital humanities and humanities in general.

How to Read Crowdsourced Knowledge

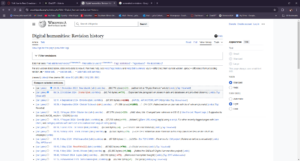
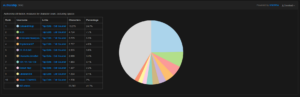
During this module, we were asked to examine the inner workings of the Wikipedia entry on digital humanities. Explicitly using the Talk and History pages to discover new information. While I have used Wikipedia for many years, I had no idea about the immense knowledge one can learn from diving deeper into the page. The history page, in particular, shows the user the revision history, as the included image shows, but it also shows who and what has been added. The revision history is essential to track how the page has changed and what and who is adding items. As the following image shows, users can also access who has contributed the most and what they said within the history. One can also click on the user’s biography to find out more about the perspective that the author is adding. One can determine pretty quickly whether the authors are someone who should be adding to the page or not.
Beyond revision and authors, the history sections show the page’s development over time. Accessing pages familiarizes users with crucial information about how that page has changed over time and, most importantly, how the field has changed. This includes when significances occur throughout time, like the release of new software or a new medium.  Digital humanities has changed immensely even in the last few years, and the Wikipedia page highlights this.

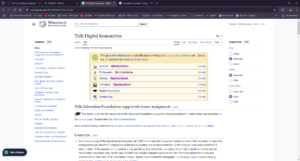
The page’s talk aspect, as shown in the image below, highlights the specific topics editors find to be of the utmost importance.

History and literature are listed as a high priority, showing what is currently emphasized in digital humanities. The talk page also shows what sources are being used and what users are debating should and should not be included. As the image

highlights that various discussions are happening regarding other sources and methods. The talk page allows the users who contribute often or rarely to engage in communal conversation to improve that page and create the best version to share with the public.

Deconstructing a Wikipedia page not only assists in gaining a better understanding of how Wikipedia pages are created and edited but also allows the user to understand who is contributing to the page. Since anyone in the public can edit, it causes misinformation and incorrect assumptions, leading to AI’s use for crowdsourcing knowledge. After evaluating and testing ChatGPT, I found that AI tools pull quite a bit of information from Wikipedia pages. This creates several issues if incorrect information is shared through Wikipedia; it is now disseminated through another source rather than just Wikipedia. Not to mention, some users could deliberately create misinformation to be shared throughout the world to further their motivations. While Wikipedia and ChatGPT can help find quick, straightforward information, one should be extremely careful when using it for more complex subjects as it can easily mislead.


Network Analysis with Gephi

Adding to the various software that we have worked with throughout this unit is Gephi, which allows the user to create network analysis graphs. Again, after viewing the example projects of Viral Texts, the Tudor Papers, and Linked Jazz, I thought I would be in way over my head. I especially felt this after viewing the Tudor Papers and the sheer number of paths that were charted with the letters and people that sent them. After I viewed the Linked Jazz project, I felt a bit better. So, when I began working on the data from the African American Films from 1909 to 1930, I better understood what I was getting myself into. Uploading the data was very simple after installing Gephi.  The first method of evaluating the data from the films was viewing the connections between the movies and actors. The below bimodal graph highlights this.

Not only can you customize the data’s color, background, and theme, but each point links you to the films the actor was in. Beyond this, you can also see the average distribution of the number of movies the actors participated in. This provides a better understanding of what the average number of films that the actors were in.

After working with the first data analysis, the second one showed the communities and connections between actors and specific films. Not only does it create groups based on shared projects, but you can also single out particular groups and evaluate the group members even closer. This fosters greater connections throughout the data. The below graph illustrates this.

Finally, when working with the data, you can expand the communities into an unimodal graph that charts all of the connections between the groups. After looking at the graph below, one begins to understand the vast network of the African American film industry in the 1900s.

Working with network analysis creates connections with the dataset and shows the broader picture of what that data is trying to tell the scholar. Gephi, in particular, was not only a relatively easy software to work with, but its vast customization and varying types of models create a wide array of options to represent one’s data.  It allows for scholars to answer basic questions such as: how are the various datasets connected? What are the patterns throughout the data? Are their specific data points more connected to others in the dataset? What is the overall significance of this data? This unit’s modules showed me the importance of data creation and representation and how much can be done with software relatively easily. Gephi unlocks the potential for researchers to create much more from their work.

Mapping with Kepler.gl

Working with digital mapping, this module truly showed me how much can be done with even a small amount of data. When viewing projects such as Photogrammer, the National Mall, and Mapping the Gay Guides, I was a bit overwhelmed by the vast extent of each project. An immense amount of time and effort seemed to go into these projects, not to mention the sheer amount of data. While this is not a bad thing, it just seemed to be a significant undertaking before I explicitly began working with Kepler. gl. It was not until I started working and using the Works Progress Administration’s Slave Narrative project that I better understood and was able to map out the locations of the various formerly enslaved individuals interviewed in Alabama. Before working specifically with Kepler.gl, I was familiar with digital mapping platforms such as Datawrapper, but I had never specifically worked with any software. Therefore, when I started working with Kepler.gl, I was pleasantly surprised when I found the software to be highly user-friendly and knowledgeable. After simply uploading data, the user can use various tools, such as different layers, to demonstrate and evaluate their data. One layer is merely pointed on the map to locate your input data. This can help you understand the overall coverage of your data.   Specifically for the slave narratives, it shows the vast space in which those were located. The graph below illustrates that.

You can also change the color of your points and the theme of the map that it is located on to assist with viewability. Another interesting layer that can be applied is a cluster layer that creates larger bubbles based on the proximity of the point’s location. Those that are large bubbles help illustrate the areas where the most people were interviewed and also show the relative location of the larger areas of enslavement. The heat map layer also shows the proximity but does so based on the color gradient of numbers. The graph below illustrates that.

Another factor that can be examined with the tools in Kepler.gl is charting the various types of slaves that those who were interviewed were. The graph below shows the varying nature of enslaved people in the house, field, or both.

Working with Kepler. gl is a valuable tool that not only can map out the locations of various data points, show the frequency for which they appear, and show varying specific information, but it can also show a timeline of when the data occurred. Data mapping not only creates another dimension to digital humanities data, but it is able to answer the questions of: where are the highest frequencies located? What changes occurred over time? Was one location’s conditions unique to that area? What are the patterns throughout the areas mapped? Digital mapping allows endless possibilities for data and for the scholar working with it, and I very much enjoyed working with Kepler.gl.


Text Analysis with Voyant

This module focused on the various forms of text analysis. When I began working on this unit, I was powerfully overwhelmed by the potential that data mining had. As someone who works in the humanities, but in history, the idea of data and vast amounts of it honestly scared me. It was not until I evaluated the various projects, such as America’s Public Bible and my favorite Robots Reading Vogue, that I better understood the importance of data mining. When I specifically worked with the data from the Works Progress Administration’s Slave Narrative Projects data, did I fully understand the critical importance and the essential questions data mining seeks to answer?

Working with Voyant, I learned the key ideas of text mining and the potential a corpus could bring, especially when working on a project with a great amount of data. After uploading the data that I was provided, Voyant created this extremely helpful textual analysis of various aspects of the narratives. Not only could one find the recurring words that appeared throughout many of the narratives, but it also allows you to see where certain words appear in the document and the context surrounding them. With Voyant, there is so much potential to evaluate trends, connections, and context throughout large data portions.

Voyant also allows the user to narrow their data into smaller subsections, such as individual states. The cirrus below is a visualization of the most common words featured in the slave narratives recorded in Missouri. Since I am from Missouri, it was fascinating to evaluate the stories of the formerly enslaved and this data in the larger picture.

This cirrus represents the most common words in Ohio, which differed from those in Missouri. Voyant allows users to compare and contrast critical factors, such as common words, throughout their different data options. This also highlights the differing experiences of the enslaved just a few states away.

Beyond the aforementioned, Voyant allows the user and creator of the data to see vast differences in frequency. In the graph below, I evaluated how the states of Missouri and Ohio differed in their use of the word “Old” in the narratives. Missouri had a much greater relative frequency for the word “old” than Ohio. This, too, highlights the importance of data mining and drawing conclusions based on the data.

Finally, this tool on Voyant summary shows the researcher various comparative issues within the data, whether it be the length of the document, the varying vocabulary, or even distinctive words. The distinctive words section is mainly what I focused on as I drew comparisons between Missouri and Ohio, as well as the larger picture of other states.

When I first began working with text mining and its surrounding process, I was terrified of what it entailed. However, after working with Voyant and seeing how significant data visualization and analysis is, I fully understand not only how important this work is, but with tools like Voyant, the process can be far simpler.

Humanities Data

The ultimate question that required an answer throughout this module was: why create data from humanities sources? Ultimately, the question of data lies in what the scholar seeks to discover. By creating data from your projects, one can find many aspects not previously understood from their work. One can discover patterns, relationships, and structures that are not apparent in reading the work. As Thomas Padilla shows in our readings, creating data creates greater possibilities for understanding and studying research. Using various tools such as data visualization, mapping, or spatial analysis allows large collections to be observed and comprehended far more easily than simple analysis. Specifically, I learned how complex and comprehensive data collection can be with our work on various projects such as the Tudor Networks, the Fairfax County Probate Records, and the Early African American Film. These projects highlighted this, but directly working with the Works Progress Administration Slave Narratives project and creating data specifically really made me realize how important creating data from documents, letters, and various other sources is to create a broader analysis field. In the case of the Slave Narratives, this data adds more humanity and greater emphasis on that individual story and how it connects to a broader context. Even though I only worked with three individuals, I felt a better connection to their story when I created their data. I also understood that with the right tools and sources, data creation is not as difficult as I once thought.

The questions that the data lets you answer that other methods do not are as follows: What patterns are seen throughout the given information?  What are the shifts and trends that occur throughout? What are common themes throughout the data? By creating data and answering these questions, the understanding of the subject is far greater than that of other projects.

When a scholar creates data from various sources, transparency is always key. The first aspect is transparency about how the scholar interpreted the data, whether it excluded certain items, created a common theme with names, and how the data was digitized. Normalization and the direct mention of this process are critical for the transparency of data creation. By explicitly stating how the data was developed and what factors created the data, the scholar creating the data has less ground for potential biases. Beyond the risk of biases, scholars can craft false arguments that would cause some to create the wrong conclusion. Specifically, stating what was undertaken to create the data and what was excluded is essential to the integrity of the field and the legitimacy of the scholar.


Why Metadata Matters

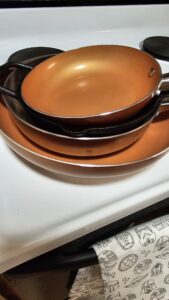
Before completing the metadata module, I had no real clue what metadata even was. I had heard the term used but had never truly engaged with it. Now, I fully understand its complexities and importance. A definition is essential to begin discussing metadata. Metadata is facts or attributes describing an item, such as a book, document, computer file, image, or artwork. These attributes are used to convey the digitized item and assist in the cataloging and processing digitized artifacts. Beyond this, it gives the item context in the greater field of research. Because of the nature of the current world, it is hard to access all material in person, and thus, the digitized image and its metadata assist immensely. In this unit, I digitized various items in my kitchen through photographs. The image below is of four skillet pans sitting on a stove. The metadata for this object is broken down into categories based on the Dublin Core metadata vocabulary. The critical pieces included are the title, the subject, a description of the photo, the source, the format, and the rights associated with the item.

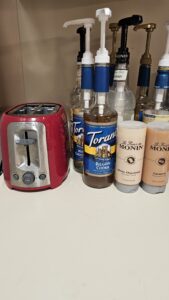
This other photo was of many of the various coffee syrups and my toaster.

Using these images, I created metadata concerning the various dimensions of the photo and attributes of valuable resources such as Tropy, where I can store all of the images and the metadata surrounding them. After exporting the metadata to Omeka, I created a cohesive and well-organized exhibit of my digitized sources and utilized the metadata. This has been an amazing learning experience for me as I have discovered all of the valuable resources available for no cost and can improve the efficiency of one’s research. Metadata gives one easy access to the rights, format, type, original location, and where the item is stored.

Metadata is essential in the digital humanities because it provides an easy means of finding crucial aspects of media included in research. The key areas of particular importance to the digital humanities are prominence information or the original location and history of the item. Without this, the item merely becomes another ordinary object. As a historian, provenance is especially important in understanding the historical context.  Another key area of essential metadata is the rights of the object. When researching, one always has to be cautious not to violate copyright and fair use, and thus, having the rights information included with the data makes it far more simplistic. Finally, understanding the creator and where the item is currently housed is essential to digital humanities scholarship. Knowing where the object was digitized and is stored helps the researcher better understand the object within the archival context. Still, it also assists in understanding if any inherent biases are present. This is crucial because these biases could potentially harm one’s research.

Digital humanities scholarship also greatly benefits from the programs Tropy and Omeka. Tropy allows for importing all objects needed to catalog and create metadata in one central location, and the interface is highly accessible for the less technologically inclined. Storing these objects and creating metadata makes one step of the research process much more manageable. Using Tropy to create metadata also allows for the export of this data into Omeka. Omeka utilizes Dublin Core metadata vocabulary that is more detailed and provides more context to the items. Beyond this, Omeka allows digital humanities scholars to create exhibits to share their resources through a digital professional environment. Omeka is also important in the metadata organization and creates another central location for the research process. Overall, using, creating, and sharing metadata through platforms like Tropy and Omeka is pivotal to the digital humanities and the future of research.